Protect sensitive input
Apply configured PII redaction and rulebook checks before content reaches the model.
SASKI SDK / Interaction governance
De-risk applications that interact with people by governing input and output, then attesting the resulting decisions.
How SASKI fits
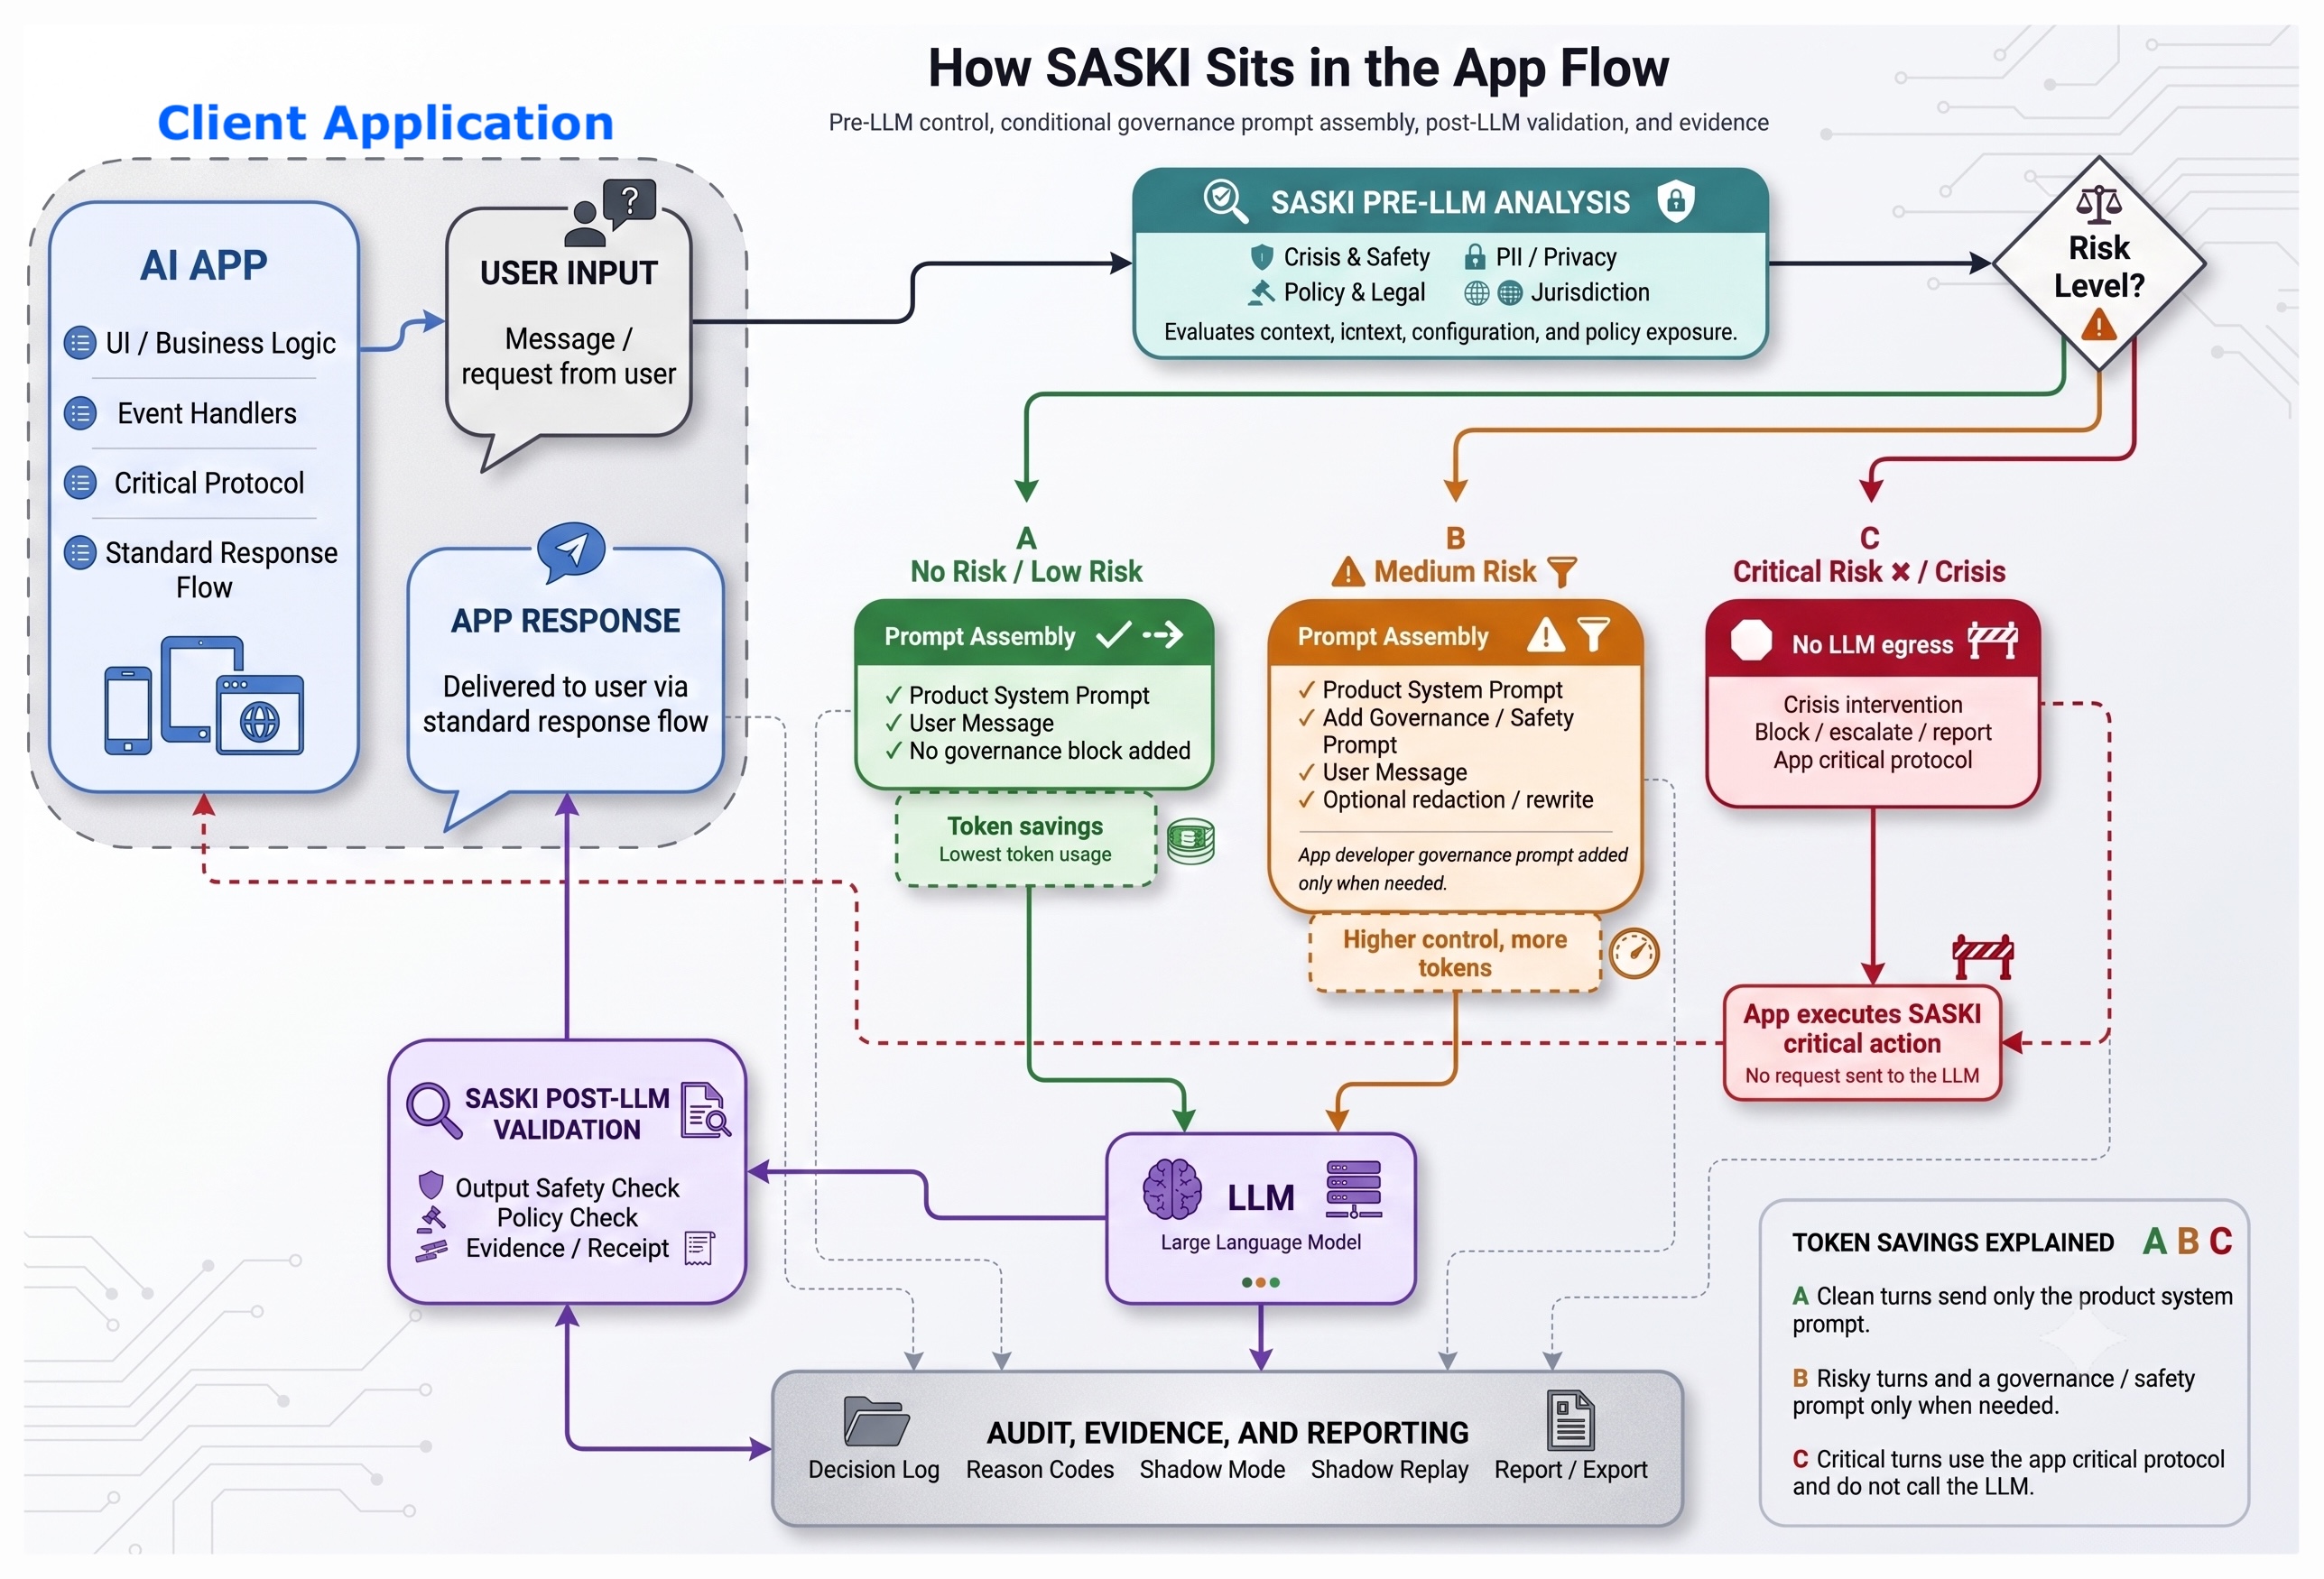
Select the diagram to open the full-size version.
Evaluate safety, privacy, policy, legal, and jurisdiction signals before content reaches the model.
Allow low-risk traffic, add configured governance for medium risk, or invoke the application’s critical protocol without calling the model.
Check model output against configured safety and policy controls before the application returns it to the user.
Produce attestation with decision details, reason codes, Shadow Mode results, replay data, and reporting evidence.
The interaction boundary
Apply configured PII redaction and rulebook checks before content reaches the model.
Use deterministic rules for crisis handling, escalation, and other consequential paths.
Evaluate the model’s output against the rulebook before returning it to the user.
Built around your context
De-risk the application with controls that reflect its users, data, and consequences.
SASKI SDK separates the governance rulebook from the model’s conversational instructions. Configure the relevant rules, test them against representative traffic, and retain attestation for the resulting decisions.
Start with an evaluation or Shadow Mode discussion to understand the decisions SASKI would make without changing production responses.
Explore the evidence behind the approach ↗Operational efficiency
Moving suitable repeated instructions into deterministic rulebooks can reduce prompt overhead. Estimate the effect using your own traffic and input-token price.
Try the Tokenator ↗Start with your use case